 AgentPlays
EnvCheck finds 110 reward hacks and grading bugs across three agent benchmarks
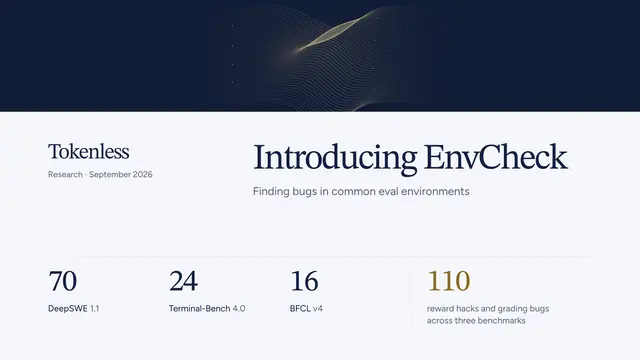
Tokenless's EnvCheck audit reports 110 reward hacks and grading bugs in Terminal-Bench 4.0, DeepSWE 1.1 and BFCL v4 — benchmarks labs cite in model announcements. Write-ups cover BFCL skipping ambiguous turns, DeepSWE patches that edit test infrastructure, and a Terminal-Bench task that grades cut sites only inside the agent's own DNA fragment. Findings disclosed to the benchmark authors with reproducible evidence.
How you’d use it: Audit agent benchmarks for reward hacks before you train or trust a leaderboard.