 AgentPlays
Inworld opens Inworld Inference, a consumer-focused LLM API with measured speed and cache gains
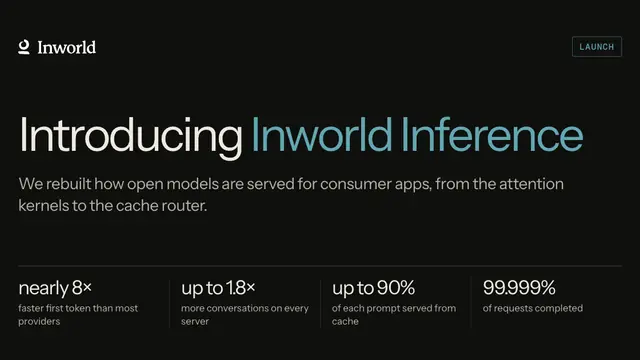
Inworld says its hosted open-model stack is live for every developer. On Gemma 4 26B it reports p95 time-to-first-token 7.8× faster than the median OpenRouter provider (0.31 s vs 2.42 s), input list price nearly 40% below that median among providers that don't train on your data, and up to 90% of each prompt served from cache. OpenAI-compatible API at api.inworld.ai/v1.
How you’d use it: Swap a slow open-model provider for faster first-token responses in a consumer chat app.