 AgentPlays
Microsoft AI finishes pre-training MAI-Base-2, a 2.8T-parameter in-house model
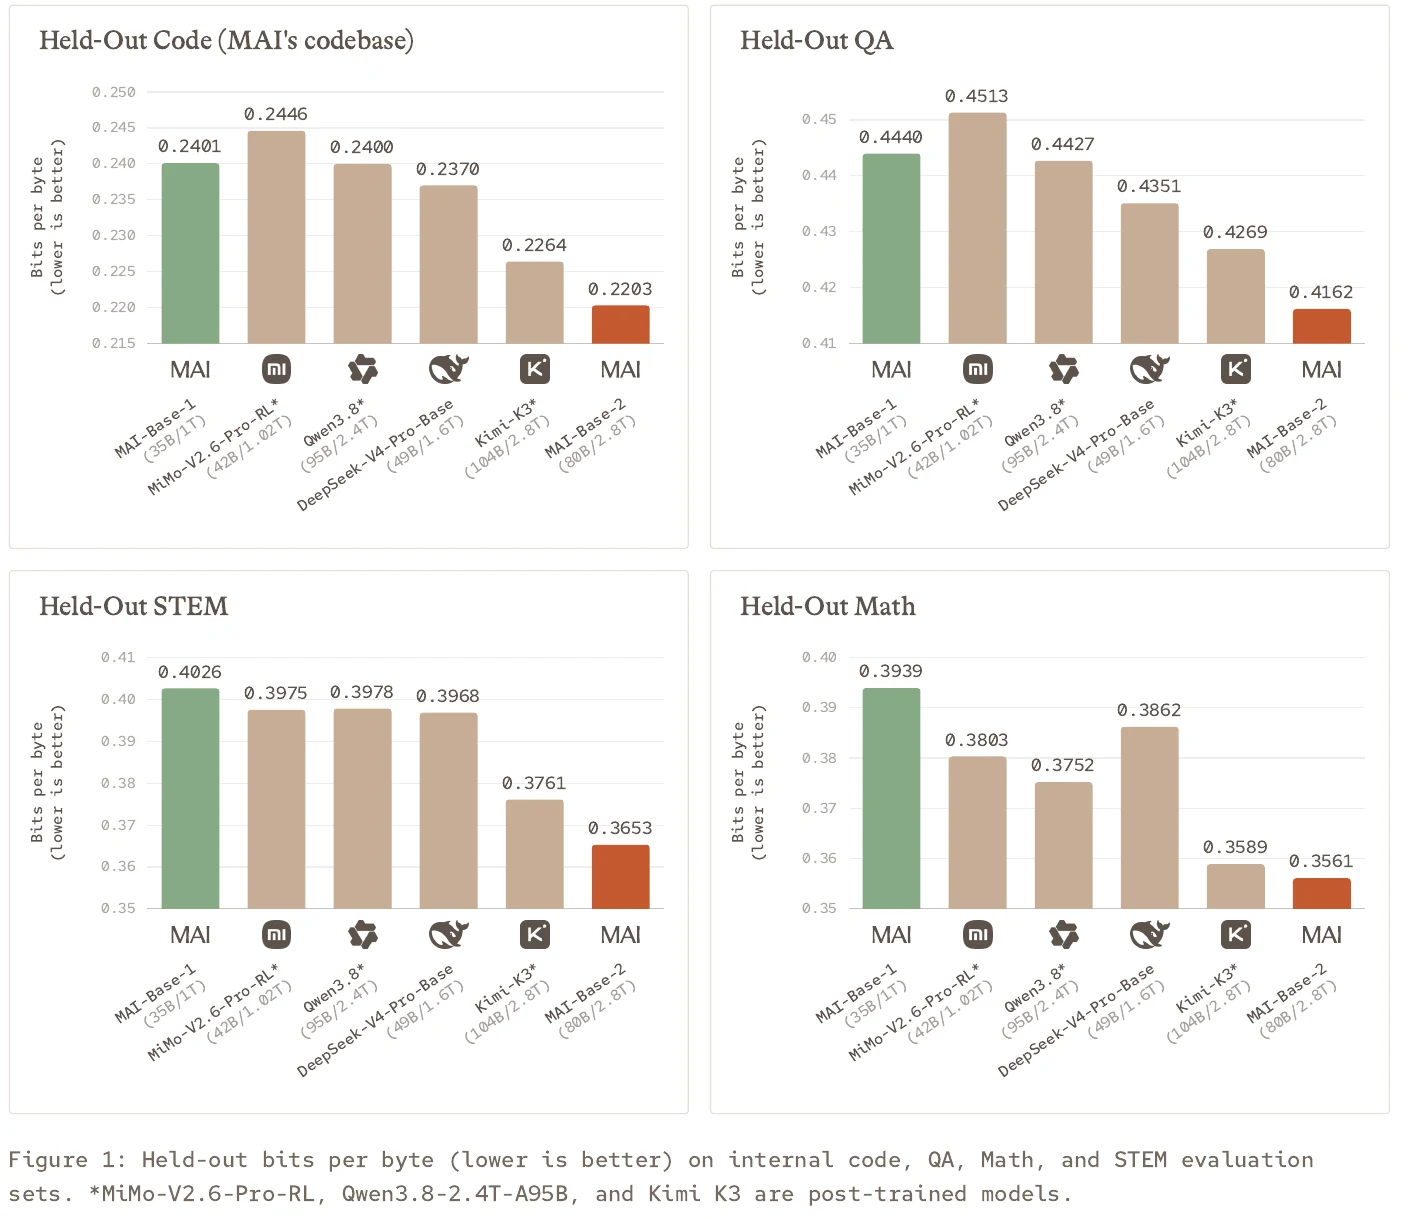
On Oct 15, Microsoft AI said it has finished pre-training MAI-Base-2, a mixture-of-experts base model with 2.8 trillion total parameters and 80 billion active. It was trained on 16,000 GB200 GPUs over 38 days in August and September 2026, on a 50-trillion-token mix with vision data from the start and a March 2026 knowledge cutoff. In Microsoft's own held-out code, Q&A, STEM and math tests, it beat every open-weight model Microsoft tested, and Microsoft estimates its recipe is 4.2 to 12.3 times more FLOPs-efficient than DeepSeek-V4-Pro-Base. Microsoft says the data is organic, with no distillation from other models, which will let it license model weights to trusted partners through Foundry. MAI-Base-2 is now in post-training; Microsoft hasn't given a release date.
How you’d use it: If your team builds on Azure, watch Foundry: Microsoft says owning its model pipeline will let it license its model weights to trusted partners there. It hasn't said when.